Study population
This study was approved by the Fox Chase Cancer Center Institutional Review Board (IRB). The Cancer Prevention Project of Philadelphia (CAP3) was established by the African Caribbean Cancer Consortium (AC3) and included persons enrolled in the US and in the Caribbean (The Bahamas and Jamaica), aged 18 or older with no known diagnosis of cancer at the time of participation (Blackman et al. 2018). A description of the CAP3 study and its recruitment strategies have been previously described (Blackman et al. 2018). Briefly, both community-based and clinic-based strategies were employed to recruit participants. Community outreach involved engaging with individuals at health fairs, community centers, and senior centers, facilitated by an established network of partnerships with key community- and faith-based organizations in the US and Jamaica. In clinical settings, recruitment was conducted in primary care and specialty clinics within the Temple University Health System (TUHS) as well as a cancer screening clinic in Freeport Bahamas. Participants were asked to complete an interviewer-administered questionnaire. After completing the survey, participants provided biological specimens, including buccal swabs or mouthwash samples and urine, for subsequent genetic and biochemical analyses. For this study only smokers, defined as individuals who were current cigarette smokers or users of other forms of tobacco (e.g., cigars) at the time of enrollment were included (N = 274). Current cigarette smokers were defined as persons who reported smoking daily or occasionally. There was one person who reported smoking cigars and was also included.
Questionnaire data
The questionnaire utilized for this study included the CaPTC-AC3 Epidemiology and Behavioral survey instrument that was culturally tailored for Black populations in the US, Caribbean and Africa (Odedina et al. 2019). Questions were adapted from the 2011 Behavioral Risk Factors Surveillance System Questionnaire and the National Health and Nutrition Examination Survey (BRFSS 2011; NHANES 1999) and details of the development of these culturally tailored measures have been previously described (Blackman et al. 2018; Odedina et al. 2019).
While the questionnaire was designed to gather a wide range of variables on participants’ demographics, health behaviors, family and medical history, this analysis focuses specifically on select demographic variables, such as gender, age, race, educational attainment, marital status, and total household income. Tobacco use behaviors were assessed, including participants’ smoking status (e.g., ever smoker or current smoker), types of tobacco used, and the quantity of tobacco consumed.
Biospecimen collection and processing
After the administration of the study questionnaire biospecimen collection included mouthwash/buccal samples for DNA extractions and germline genotyping as well as urine for biomarker analyses of tobacco metabolites.
Mouthwash/buccal samples: Participants were required to refrain from eating and drinking at least 30 min prior to performing the mouthwash rinses. Each participant was provided a 50 mL Falcon™ tube and a 30 mL specimen cup containing 10 mL of Scope and instructed to gargle while tilting their heads back for 30–60s before spitting it back into the 50 mL tube. Mouthwash samples were transported at room temperature to the laboratory for processing. Samples were centrifuged, and the mouthwash supernatant was removed, and DNA extraction was performed from the oral exfoliated cell pellet using the QIAGEN PureGene DNA extraction protocol (Qiagen 2014). DNA quality was assessed for each sample and tested for beta-globin to confirm presence of amplifiable DNA.
Urine samples: Participants were instructed by study staff on how to conduct a clean catch urine collection (Linda and Vorvick 2024) and the participant self-collected in the nearest restroom. Urine samples were transported to the laboratory, at 4 °C (on ice packs), where they were aliquoted and stored at − 80 °C.
NNAL biomarker measurements
4-(methylnitrosamino)-1-(3-pyridyl)-1-butanone, or NNK, is a tobacco-specific N-nitrosamine that is found in tobacco and tobacco products. Exposure to NNK occurs via direct inhalation of tobacco smoke (from smoking of from second-hand exposure) as well as through oral absorption by smokeless tobacco products, or absorbed through exposure to the surface of the skin (Wei et al. 2016). NNK is a well-established carcinogen that is metabolized to NNAL, a stable, biomarker that can be measured in urine using well established standardized laboratory protocols. The biomarker assay is sensitive enough to detect tobacco exposure in smokers and in second-hand smokers and is tobacco-specific in that it is not a dietary component and is only found in the environment when there is tobacco smoke present.
Metabolism of NNAL was performed on each participant sample by the Nicotine and Tobacco Product Assessment Shared Resource (NicoTar) Laboratory at the Roswell Park Comprehensive Cancer Center, Buffalo, NY. The assessment involved determination of the concentrations of free and total NNAL concentrations using the modified method described by (Jacob et al. 2008). Briefly, 1-ml samples (urine, QCs, calibration standards, and control blanks) were transferred into test tubes. NNAL-d3 (internal standard, Toronto Research Chemicals, Toronto, Ontario, Canada) and sodium potassium phosphate buffer were spiked in the individual samples.
The samples for measurement of total NNAL (i.e. Free (NNAL) and Conjugated (NNAL-Gluc) analysis were incubated with β-glucuronidase (Sigma Lot # SLCC9103) enzyme at 37 °C for 12 h, whereas the samples for measuring free NNAL skipped the enzyme cleavage step. A series of liquid-liquid extraction and derivatization was applied to all the samples. The products were evaporated to dryness in a SpeedVac, reconstituted in methanol containing hydrochloric acid and then transferred to Total Recovery LCMS Vials (Waters Corp.) for analysis. NNAL analysis was performed using Waters Xevo® TQ-XS Tandem Mass Spectrometer with ACQUITY UPLC I-Class Chromatography System (UPLC-MS/MS) using a modified method (Jacob et al. 2008). The concentration of NNAL-Gluc was calculated by subtracting concentration of free NNAL from the concentration of total NNAL (i.e. NNAL-Gluc = Total NNAL- Free NNAL). In addition, urinary creatinine was measured in all urine samples for NNAL normalization and urine flow correction. For normalization of Total NNAL and Free NNAL (pg/mg):
$$ }\;}\;} = }\;}/} \times 100 $$
$$ }\;}\;} = }\;}/} \times 100 $$
$$\begin}\;} - } = }\;}\;} -}\;}\;}.\end $$
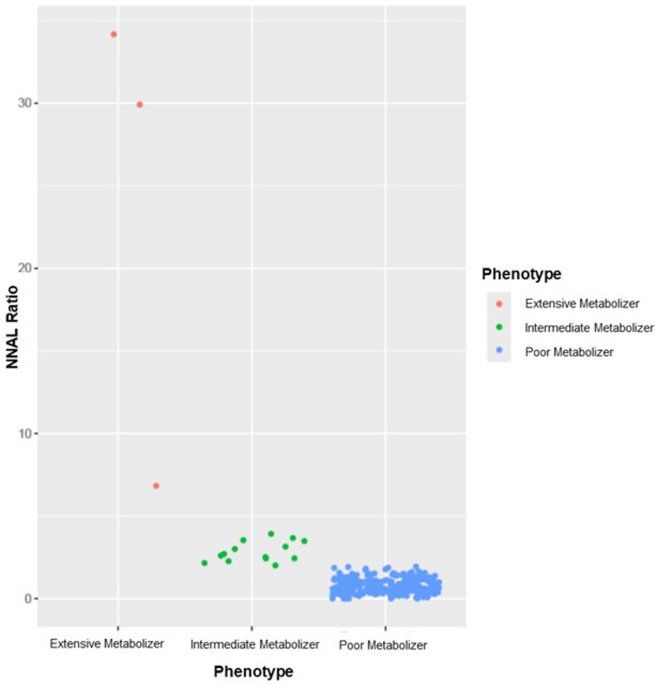
Lastly, using these data, NNAL detox ratio was calculated (NNAL detox ratio = Normalized NNAL-Gluc/Normalized Free NNAL) for each study participant and was classified as: poor (ratio < 2), intermediate (ratios 2–5), and extensive (ratio > 5) tobacco metabolizers. In this analysis metabolizer phenotype was re-categorized as poor (ratio < 2) or extensive/intermediate (ratio ≥ 2) groups. Metabolizer classification cutoffs were based on (Bhat et al. 2011), who used the ratio of NNAL-glucuronides to free NNAL to define poor, intermediate, and extensive metabolizers in the context of a validated LC/MRM-MS assay. We applied these published thresholds to align with an established analytical framework and enhance comparability with existing literature. Glucuronidation is the primary detoxification pathway for NNAL excretion. A high NNAL ratio (Normalized NNAL-Gluc/Normalized Free NNAL) indicates more efficient metabolism, with a greater proportion of NNAL converted to its glucuronidated form (consistent with intermediate or extensive metabolizer phenotypes). In contrast, a lower ratio reflects reduced metabolic efficiency, with higher levels of free (unconjugated) NNAL and greater potential for prolonged carcinogenic exposure.
Samples were submitted to the (NicoTar) Laboratory in three batches, with batch 2 and 3 including 10% of the samples from the previous batch repeated as batch controls (i.e. batch #2 included 16 samples from Batch #1, and Batch #3 included 14 samples from Batch #2). Each batch also included 2 samples from participants who reported as non-smokers as negative controls. Each batch also included laboratory control blanks and calibration standards based on standard protocols. For samples that resulted in NNAL readings below the limit of detection, the limit of detection for that batch was divided by the square root of two (1.414) and was inputted as a value for these samples to calculate the NNAL detox ratio. This is a standard approach for previous studies (Bhat et al. 2011).
Genotype data
Genotyping: was performed on all germline DNA samples using a customized genotyping array manufactured by Illumina which includes all probes from the InfiniumTM Global Screening Array v3.0 bead arrays (654,027 markers) and 11,377 markers we have identified as Ancestry Informative Markers (AIMs) (Boudeau et al. 2023).This genotyping array originated from a previously developed and validated comprehensive panel of African ancestry-informative markers to improve detection of population structure and enable more accurate investigation of ancestry-related disease risk (Boudeau et al. 2023). Our AIMs included Single Nucleotide Polymorphisms (SNPs) identified within 1 Mb of genes involved in addiction, DNA repair, metabolic activation and detoxification of carcinogens (Phase I and II pathway genes e.g. Cytochrome P-450(CYP) and Glutathione S-transferases), and efflux of drug, hydrophobic agents other agents found in cigarette smoke (Phase III pathway genes e.g. classes of ATP Binding Cassette (ABC) transporters). Our final SNP lists include 9,514 AIMs which were considered successful post analysis determined by Illumina standard and also have been successfully genotyped in all our samples. This analysis focused on Phase I, II and III AIMs only.
While race was collected and reported as self-identified, analyses were not conducted as direct comparisons between self-identified racial groups. The study was designed to evaluate genetic ancestry which was determined and calculated as Ancestry proportion for each patient sample. 223,637 SNPs shared between 1000G normal samples, and our cohorts were used for ancestry proportion analysis. We used YRI and CEU population from the 1000G project as reference(Genomes Project et al. 2015) for this estimation. Estimated individual ancestry proportions for all samples were calculated using ADMIXTURE (Alexander et al. 2009).
While sex was collected as self-identified, genotyped sex was determined and confirmed for each study sample via the proportion of calls on Y-loci. When there were sex discrepancies between self-reported and genotype sex, the genotype sex was reported.
Functional analysis of SNPs
Regulome Database: To determine functional context to SNPs we generated Regulome dB Scores for each. The Regulome database annotates SNPs identified in functionally active regions of the genome based on functional genomic assays such as Transcription Factor (TF) ChIP-seq and DNase-seq (from the ENCODE database) as well as those overlapping the footprints and QTL data. Regulome scores range from 1 to 7 along with supporting available data. The lowest score of 1 indicates the higher the likelihood that the SNPs are functionally significant. Regulome scores are interpreted as follows: 1a = eQTL/caQTL + TF binding + matched TF motif + matched Footprint + chromatin accessibility peak; 1b eQTL/caQTL + TF binding + any motif + Footprint + chromatin accessibility peak; 1c eQTL/caQTL + TF binding + matched TF motif + chromatin accessibility peak; 1d eQTL/caQTL + TF binding + any motif + chromatin accessibility peak; 1e eQTL/caQTL + TF binding + matched TF motif; 1f eQTL/caQTL + TF binding / chromatin accessibility peak; 2a TF binding + matched TF motif + matched Footprint + chromatin accessibility peak; 2b TF binding + any motif + Footprint + chromatin accessibility peak; 2c TF binding + matched TF motif + chromatin accessibility peak; 3a TF binding + any motif + chromatin accessibility peak; 3b TF binding + matched TF motif; 4 TF binding + chromatin accessibility peak; 5 TF binding or chromatin accessibility peak; 6 Motif hit; 7 Other (Boyle et al. 2012; Dong et al. 2023).
Molecular Modeling: The only two SNPs that encode a missense change in amino acids were subjected to molecular modeling, a computational method that goes beyond the conventional analyses found in public databases to predict whether the given SNP will yield deleterious effects on protein function. This method not only accounts for the structural changes from sidechain substitutions, but also surface accessibility changes and the ensuing effects on protein assemblies. The SNP amino acid change was mapped onto the three-dimensional coordinates for the protein structure of the gene. Paying attention to the 3D location and molecular details helps to characterize the SNP based on the predicted ability to modulate the corresponding protein function of the gene. Using AlphaFold structure predictions we can make better pathogenicity predictions and rationalize its effect on protein function. Specific modeling methods are as follows:
Structural Modeling of CYP3A5 Isoforms - The canonical full-length human Cytochrome P450 3A5 protein (UniProt ID: P20815) structure was experimentally determined by X-ray crystallography (PDB ID: 5VEU), which includes the Heme cofactor essential for enzymatic activity. To model the CYP3A5*3 isoform resulting from the rs776746 polymorphism, which lacks the N-terminal 113 amino acids, AlphaFold3 (AF3) (Abramson et al. 2024) was employed to predict the structure of the truncated variant. Structural alignments and visualization were performed using ChimeraX (Meng et al. 2023).
Modeling of ZNF789–TRIM28 Protein–Protein Interaction - Protein sequences and domain boundaries for ZNF789 (UniProt ID: Q5FWF6) and KAP1/TRIM28 (UniProt ID: Q13263) were curated from UniProt. Initial AlphaFold3 modeling was conducted using full-length canonical sequences to identify potential interaction regions. Subsequent models focused on the KRAB domain of ZNF789 (residues 1–100) and the coiled-coil region of TRIM28 (residues 245–345), using AlphaFold3 and ColabFold (v1.5.5) (Mirdita et al. 2022) with increased sampling (n = 40 models per complex). Structural analyses, including super-positioning of protein complexes, analysis of interfaces and contacts, and figure preparation were done with ChimeraX (Meng et al. 2023).
Variant Effect Prediction Using AlphaGenome - To assess the potential regulatory impact of candidate SNPs, we performed in silico variant effect prediction using AlphaGenome(Avsec et al. 2026), a sequence-based deep learning model developed for predicting regulatory variant effects across multiple genomic modalities. For each candidate SNP, genomic coordinates, reference allele, and alternate allele were used as input to AlphaGenome. Variant effects were estimated by comparing model predictions from the reference and alternate allele sequences at the same genomic locus. The predicted effect score was calculated as the difference between alternate-allele and reference-allele predictions. AlphaGenome predictions were used as functional annotation evidence to support interpretation and evaluation of the regulatory activity of SNPs identified from Firth penalized logistic regression models.
Statistical methods
Univariate analyses: Socio-demographic characteristics (such as race, sex, age, marital status, income, and education) of all recruited healthy smokers were summarized using descriptive statistics. Fisher’s exact tests were used to examine the associations between AIMs and poor metabolizer phenotype.
NNAL measurements such as normalized total NNAL, normalized free NNAL, normalized conjugated NNAL and NNAL ratio were summarized using descriptive statistics (such as mean and standard deviation) for the entire cohort as well as for various subgroups identified by age and gender. Our initial analyses revealed a significant amount of missing data for pack years (> 60% missing), however data for cigarettes per day was more complete with only ~ 8% missing. The Kruskal–Wallis test was used to assess the relationship between each NNAL variable and the sub-groups. All univariate tests were two-sided and used a 5% Type I Error to determine statistical significance. Computations were performed using the R language (R Core Team 2021).
Multivariable analyses: The analysis primarily focused on the 178 AIMs corresponding to the phase I, II and III genes; of these, one SNP contained a value for only one genotype and was excluded from further analysis. Genotype was coded as 0, 1 or 2 and was treated as a quantitative variable. Ancestry information (in the form of YRI ancestry proportion taking value between 0 and 1) was matched to clinical and genotype data. A multivariable penalized logistic regression model was fit to each AIM to determine the strength of association between metabolizer phenotype, as defined earlier, and genotype after adjusting for confounders such as age, sex, number of cigarettes smoked per day and assay batch. Statistical significance of the association was first assessed using nominal p-values. P-values were then adjusted for multiple comparisons using the Benjamini-Hochberg false discovery rate (FDR) method. SNPs with p < 0.05 and FDR ≤ 0.2 were considered statistically significant. SNPs with p < 0.05 but FDR > 0.2 were considered nominally significant but did not meet the predefined multiple testing threshold. In addition, SNPs with p ≤ 0.1 that did not meet the FDR threshold were considered suggestive and included for exploratory analyses. These findings are interpreted as hypothesis-generating. For each SNP, odds ratios (OR) and corresponding 95% confidence intervals (CI) were computed to further quantify the degree of association between metabolizer phenotype and genotype. Furthermore, a multivariable LR model was fit to determine the strength of association between metabolizer phenotype category and ancestry proportion after adjusting for confounders such as age, sex, number of cigarettes smoked per day and assay batch. Since the genetic variants evaluated are AIMs, and the primary objective is to examine the relationship between genetic ancestry and NNAL metabolizer phenotype, population structure is intrinsic to the exposure of interest rather than a confounder that can be fully adjusted for without attenuating the signal under investigation. Furthermore, the study population was predominantly composed of individuals of African ancestry (Table 1), reflecting continuous variation in admixture rather than discrete population subgroups. Therefore, we did not control for population stratification.
Table 1 Sociodemographic Characteristics of all recruited smokers (n = 274) 

Comments (0)